Certifications vs Real Experience: How to Validate IT Infrastructure Candidates Before You Hire
October 20, 2026
MERN vs MEAN vs Java Full Stack: Which Full Stack Developer Does Your Product Need?
October 26, 2026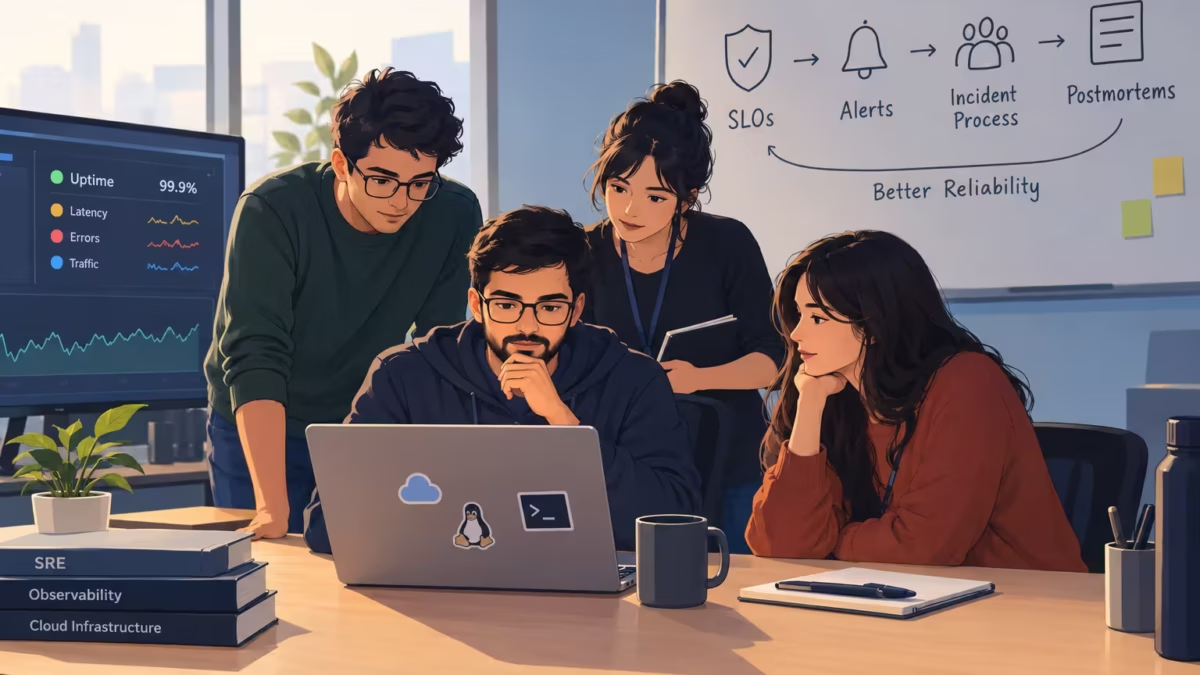
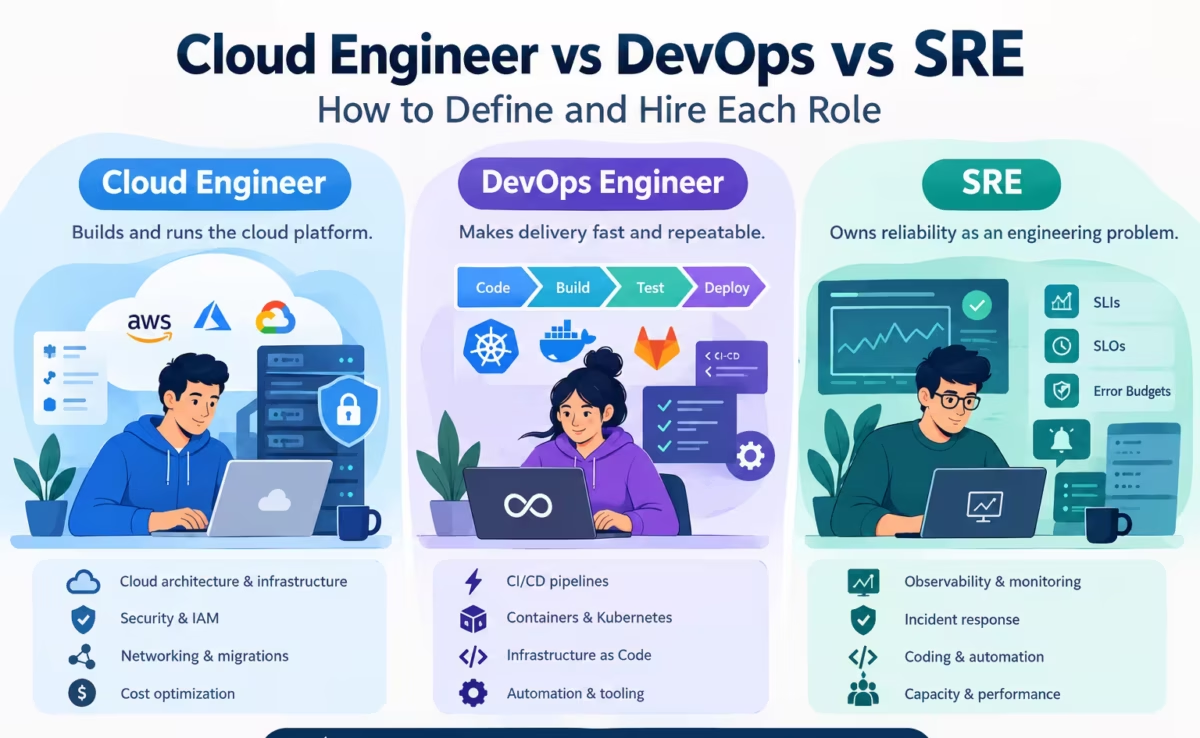
Most companies do not decide to hire an SRE. They go back into it. The pages at 2am keep coming, the developers are quietly burning out on call and one day someone says out loud what everyone’s been thinking: we need someone whose actual job is keeping this thing up. If that is roughly where you are, this is for you. Not another piece explaining how SRE differs from DevOps or cloud engineering, you have likely sorted that out already, but a practical guide to when you are genuinely ready and what that first hire should own once they arrive.
Getting this right matters more than it looks. The first SRE sets the template for everything that follows, so a strong one compounds and a weak one leaves you worse off than before.
The signs your team is ready for its first SRE
There is no single moment that announces it. Instead, a few patterns tend to show up together and once you recognise two or three of them, you are probably past due.
The clearest sign is repeated incidents. The same kinds of outages keep happening, you fire them and then they happen again because nobody owns prevention. You are stuck reacting, never getting ahead of it. That loop is exactly what an SRE exists to break.
Next is developers handling on-call by default. Your engineers built the product and now they are also the ones woken up when it breaks, with no real system behind it, just whoever's guilt tripped into answering. It drains them, pulls them off feature work and it does not scale. When on call is an accident rather than a design, you need someone to own it properly.
Another tell is no agreed uptime targets. Ask around and nobody can actually say how reliable the system is supposed to be. Is 99.9% fine? Is an hour of downtime a crisis or a shrug? Without agreed targets, every incident becomes an argument about how much it mattered and you are flying blind on reliability.
And finally, a big launch or traffic jump is coming up. A major product launch, a marketing push, a seasonal spike, anything that is about to put real load on your systems. The worst time to discover you have no reliability practice is while it is buckling under traffic. Bringing someone in ahead of that is far cheaper than scrambling during it.
None of these alone is a crisis. Two or three together is your signal.
What your first SRE should own in the first few months
Here is a mistake companies make: they hire a Site Reliability Engineer and then bury them in whatever’s on fire that week. The first few months should be about building foundations, not just fighting flames. A strong first SRE focuses on a handful of things that pay off for years.
Defining SLOs. Service Level Objectives are the backbone of the whole discipline, the agreed answer to “how reliable should this be?” Your first SRE should work with the team to set realistic, measurable targets, so reliability stops being a vibe and becomes something you can actually track and make decisions against.
Cleaning up alerting. Most teams that haven’t had an SRE are drowning in noisy, meaningless alerts, the kind everyone learns to ignore, which is how real problems slip through. Early on, the SRE should prune the noise so that when something pages a human, it genuinely matters. Alert fatigue is a reliability problem in its own right.
Setting up an incident process. When things break, there should be a known way to respond, who does what, how it is communicated, how it gets resolved, instead of chaos and a scramble every time. Your first SRE builds that muscle, so incidents become managed events rather than panics.
Running postmortems. After an incident, the point is not blame, it is learning. The SRE should establish blameless postmortems that turn each outage into a concrete fix, so the same failure does not keep recurring. This is how that repeated incident loop finally gets broken.
Taken together, these are what a site reliability engineer roles and responsibilities list actually looks like in practice for a first hire: less heroics, more systems that stop the heroics being necessary.
Why your first SRE needs to be senior
This is the part people underestimate and it costs them. Your first SRE should almost always be more senior than the SREs you hire later and the reason is simple: there is nobody for them to learn from.
A later SRE joins an existing practice, with SLOs in place, processes defined and seniors to mentor them. Your first one is building all of that from nothing, alone, often while also educating the rest of the company on what SRE even is. That takes someone who has done it before, who knows what good looks like and who has the judgment to make the right trade offs without a safety net. Hire too junior for this role and you get someone who needs the very guidance that does not exist yet. It is a false economy. Pay for the experience here; it is the one SRE hire where seniority is not optional.
A job description outline for your first SRE
When you write the role, keep it focused on ownership and foundations rather than a laundry list of tools. A workable outline:
- Role summary: Own and build the reliability practice from the ground up, defining how the organisation measures, protects and improves system uptime.
- Key responsibilities: Define and track SLOs; overhaul alerting and monitoring; establish the incident response process; run blameless postmortems; improve system reliability and performance; partner with developers on building for resilience.
- Required site reliability engineer skills: Strong systems and cloud infrastructure experience; solid coding ability (automation, tooling); deep familiarity with monitoring and observability; incident management experience; and the communication skills to influence a team that is new to SRE.
- Seniority: Senior, with proven experience setting up reliability practices, not just maintaining existing ones.
That last line is the one most job descriptions get wrong. Make it explicit.
Interview questions that actually test the role
Skip the trivia. For a first SRE, you want to probe judgment under pressure and the ability to reason about trade offs. A few that work:
- “Walk me through a serious incident you handled. What did you do in the moment and what did you change afterward?” You’re listening for calm, structured thinking and crucially, the follow-through, the fix that stopped it recurring.
- “How would you set an SLO for a service that’s never had one? What target and why?” This tests whether they can reason about reliability pragmatically rather than reaching for an arbitrary 99.99%. What does a site reliability engineer do if the business wants more reliability than the budget allows? The answer reveals how they handle trade-offs.
- “When would you tell a team to slow down feature work to pay off reliability debt, and how would you make that case?” This surfaces their judgment and their ability to influence, both essential when they’re the lone voice for reliability.
- “Tell me about an alert system you cleaned up. How did you decide what to cut?” Practical, revealing and hard to fake if they’ve actually done it.
Strong candidates answer these with specifics and scars. Weak ones stay abstract.
Proof it pays off: a SaaS success story
The value of getting this hire right is not theoretical. In one engagement, a US based SaaS company needed to strengthen the engineering backbone behind a product its customers depended on daily. Rather than spreading reliability work thinly across already stretched developers, placing the right senior engineer to own that function gave the company a single point of accountability for uptime and performance and the foundations to scale without the constant firefighting. The right hire, brought in at the right moment, was what let the team get ahead of its reliability problems instead of forever chasing them.
How Prism HRC helps you hire your first SRE
Hiring your first SRE is genuinely harder than hiring your fifth, because you cannot lean on an existing team to vet them and the seniority bar is higher. That is exactly where getting the screening right matters most.
At Prism HRC, we help companies hire site reliability engineer talent who can build a reliability practice from scratch, not just maintain one someone else set up. Our technology recruitment teams screen for real incident handling experience, SLO judgment and the senior level ownership a first hire demands, so the profiles you see are matched to the weight of the role. For permanent, contract, project and contract to hire requirements, Prism HRC helps you find the SRE who sets the right foundation.
Ready to hire your first SRE?
Prism HRC finds senior engineers who can build your reliability practice from scratch.
Frequently Asked Questions (FAQs)
Tell Us Your Requirement
Ready To Build Your Dream Team With Prism HRC?
Want to explore our range of recruitment, staffing, payroll, compliance, employee welfare and employee global mobility solutions? Fill out this form and our subject matter experts will get in touch with you within 2 working days to address all your requirements at length.
Note to Candidates: Please DO NOT use this form to career related queries or job applications, as all such requests will be DELETED. For any job/career related queries, please go to career page.